Guignet_
Benchmark AI agents on the code that actually matters—your own.
A local-first evaluation system that mines real Git history into replayable tasks and produces validity-checked, judge-free agent benchmarks.
How it works
Mine real Git history
Replay and gate tasks
Run, score, and report
The problem
Public coding benchmarks are measured on somebody else’s repositories and are increasingly vulnerable to saturation or training-data contamination. Private evaluation platforms can require uploading the very code a team most needs to protect.
Guignet makes the target repository the benchmark. It reconstructs real tasks from Git history, validates that each task is genuinely solvable, runs agents in isolated worktrees, and scores their changes against held-out tests.
The pipeline
- Mine finds task-shaped commits and reconstructs a prompt, base commit, hidden fix, and hidden verifier.
- Gate proves that the verifier fails before the fix and passes after it, repeatedly rejecting flaky tasks.
- Run executes multiple attempts through a model adapter in disposable worktrees.
- Score applies each answer against the held-out verifier without an LLM judge.
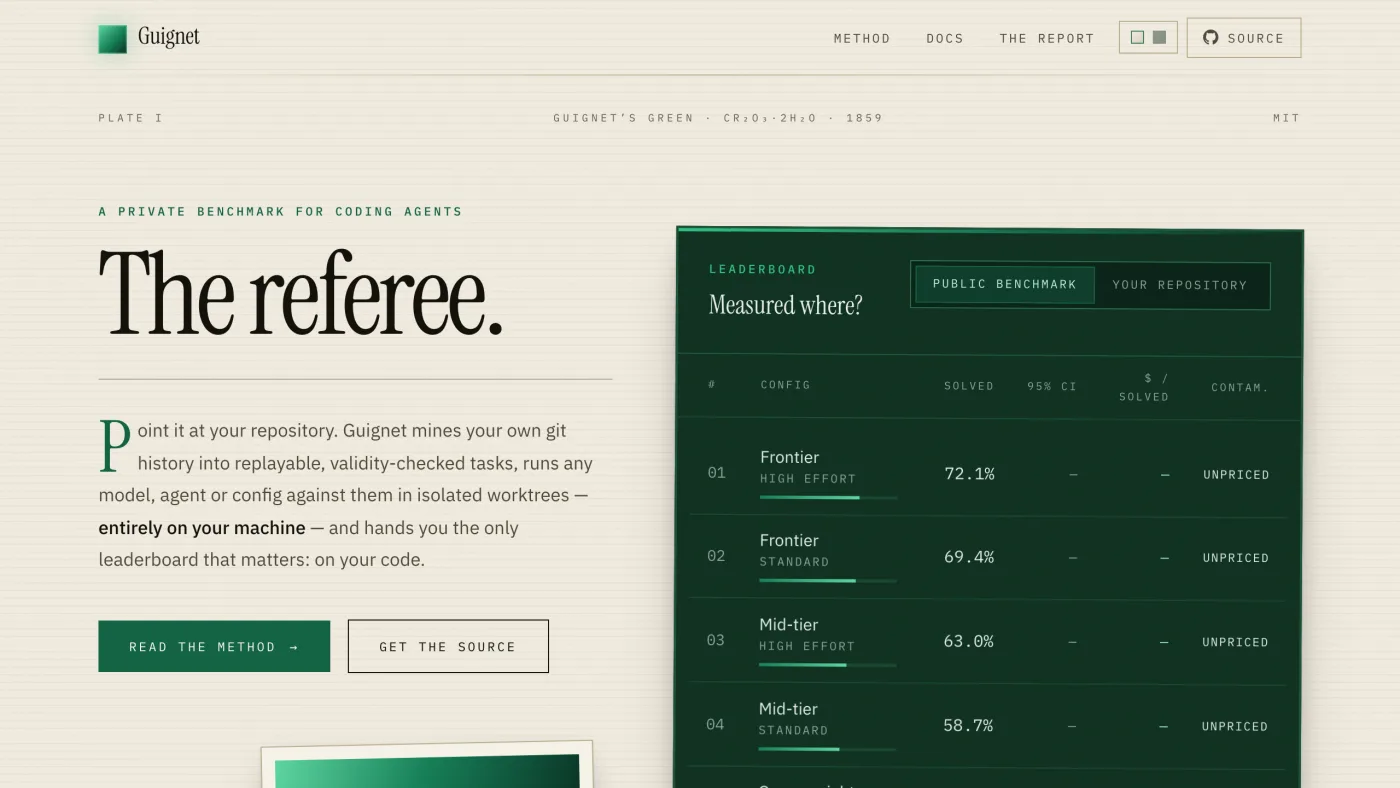
- Report creates an offline HTML leaderboard with confidence intervals, cost, soundness, and contamination controls.
Built for real machines
Benchmarking is background work, so Guignet monitors CPU and memory pressure before adding concurrency and lowers scheduling priority for spawned processes. Runs are resumable, budget-capped, and designed to make progress without monopolizing the host.
Evidence over theater
The repository includes a full methodology, stable CLI contracts, contamination analysis, and a working end-to-end pipeline dogfooded on both private production code and the public Hono framework.
Current status
The complete mine → gate → run → score → report workflow is operational. Guignet is still pre-1.0 while its reporting and platform support continue to harden.